Kafka data skew
- kafka
- synthetic-data
😱 Almost everyone in Kafka-land knows about the problem of data skew, but no one tests for it.
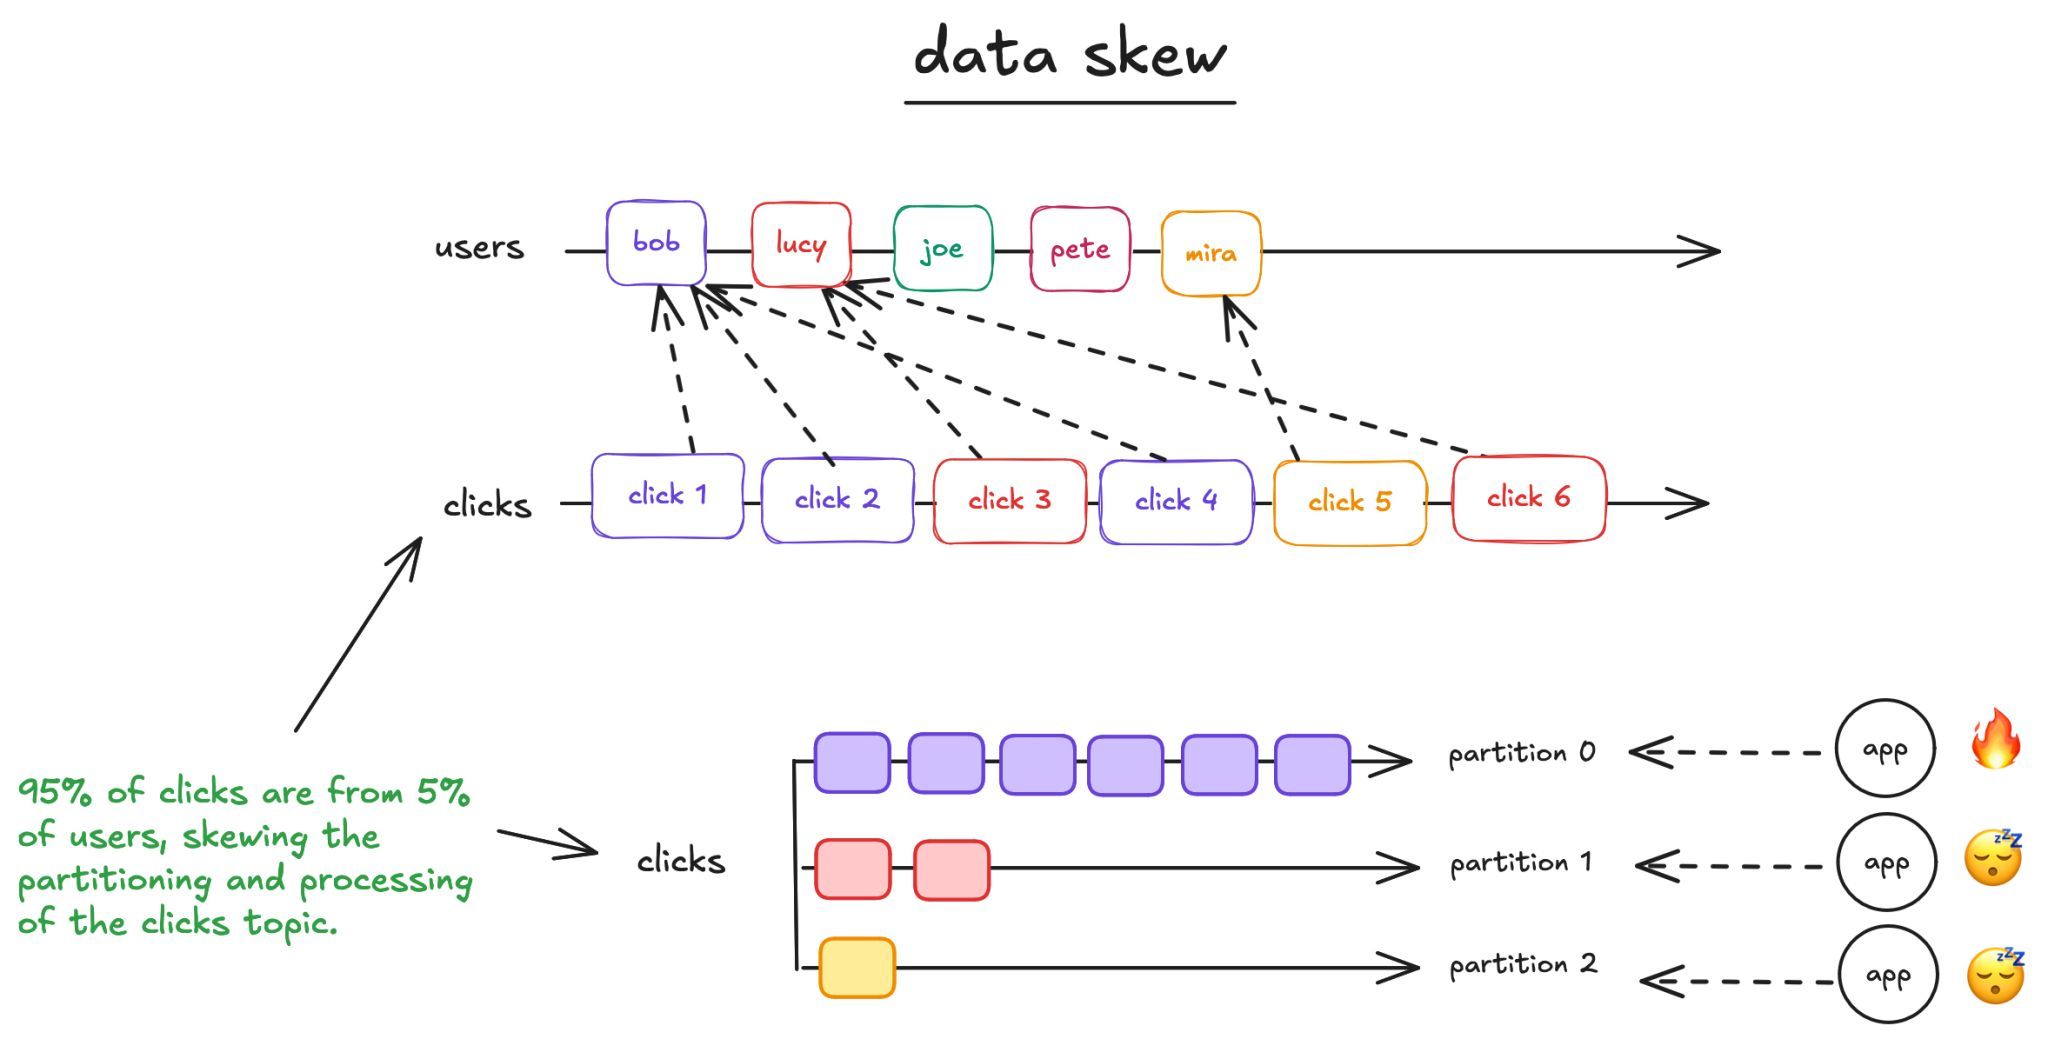
What is it?
Most data isn't evenly distributed. Take a very realistic clickstream example. What happens if 95% of clicks come from 5% of your users?
The amount of data that resides in each partition gets skewed, and your applications can behave slow and weird.
To handle that, most engineering teams do one of 3 things:
(1) ☠️ Nothing, and pray it all works out.
(2) 💔 Test only the brokers, writing large amounts of random bytes and seeing if the weakest node can keep up. This gives you a false sense of confidence because you're not testing the hardest part (your apps)
(3) 🎲 Generate test data that randomly pairs up users and clicks, hoping some skew will incidentally occur.
The right thing to do is generate skewed streams during testing. As you write events, you index them in such a way that they can be efficiently looked up later with a moving bias.
I put a lot of hard work into ShadowTraffic's ability to do that invisibly, tucking it all behind a simple function. 😮💨